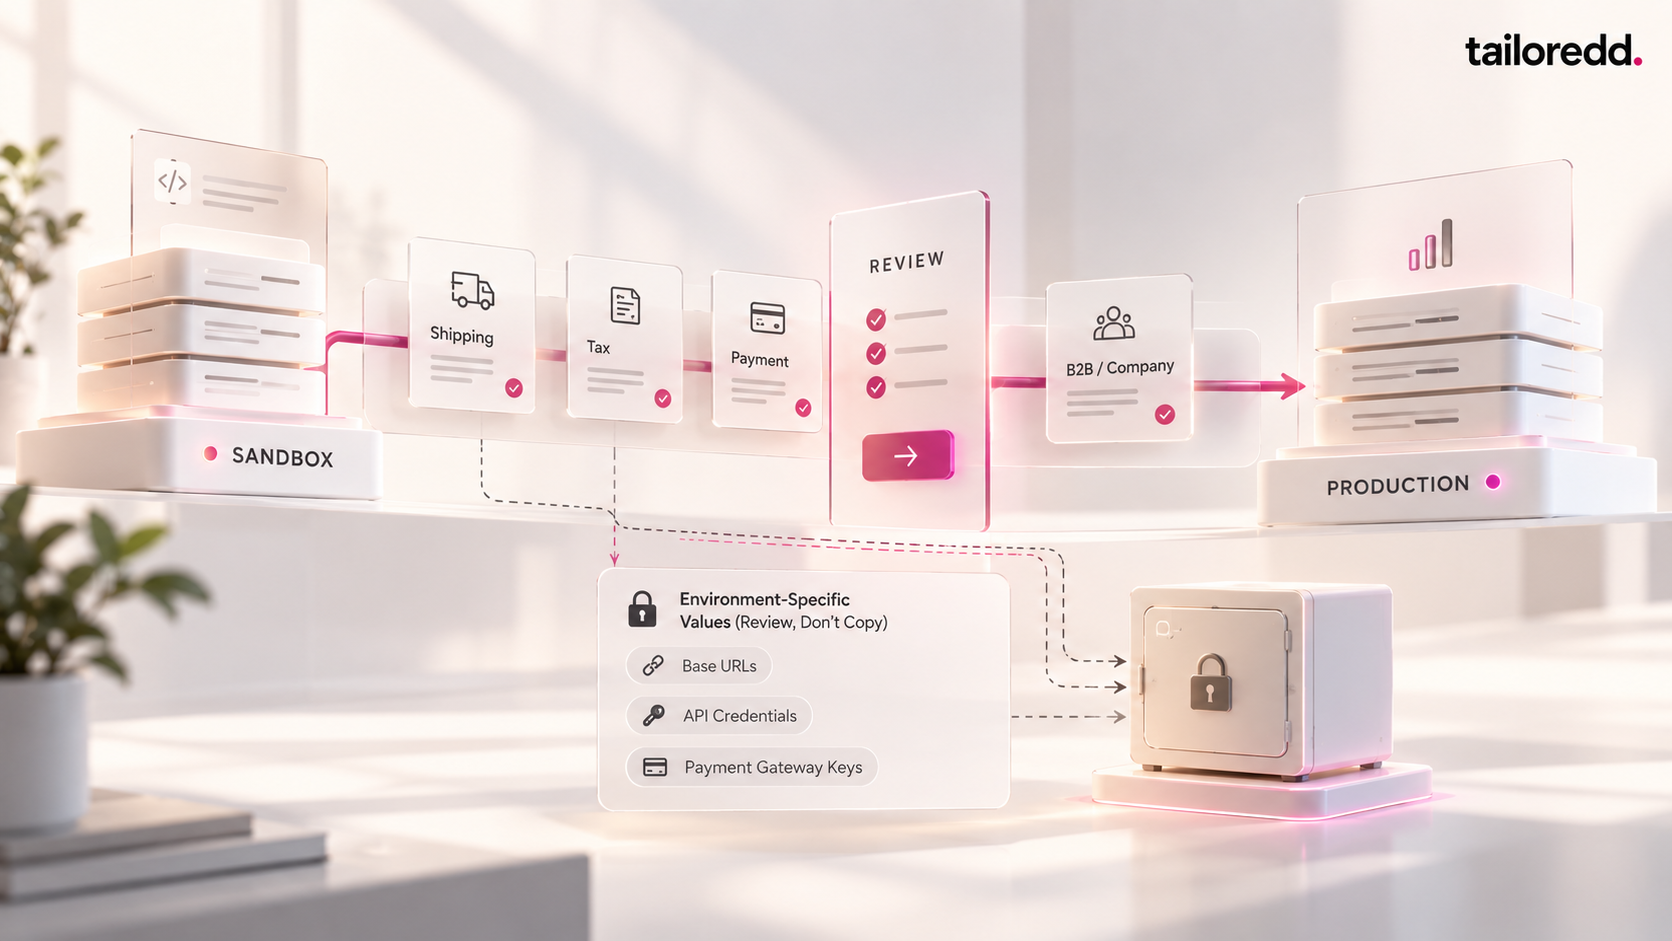
Adobe Commerce just removed one of those jobs enterprise teams quietly hate: rebuilding tested configuration by hand in production.
The new configuration API can move settings from sandbox to production programmatically.
That sounds like a deployment convenience. It is.
It is also a very efficient way to copy the wrong payment key, base URL or environment-specific setting into a live store.
The interesting question isn’t whether commerce configuration can now be automated.
It is which configuration should be.
What Adobe actually changed
Adobe Commerce as a Cloud Service added two REST operations to production on September 8:
GET /V1/system/config
and
PUT /V1/system/config
They provide programmatic access to system configuration that would otherwise be managed through Commerce Admin.
Adobe specifically lists store information, shipping and tax settings, payment-method settings, and B2B/company settings among the supported configuration areas. (Adobe Developer)
The intended workflow is straightforward.
Read selected configuration from sandbox. Review it. Write the approved values into production.
That middle step matters enough that Adobe’s own documentation explicitly warns teams to remove values that should not travel between environments, including base URLs, API credentials and payment-gateway keys.
This is not a database cloning API.
It is not an instruction to make production identical to sandbox.
It is a mechanism for treating selected commerce configuration more like deployable configuration.
That distinction should shape the implementation.
The old problem wasn’t just manual work
Most mature commerce teams already have some form of deployment discipline around code.
A storefront change goes through source control. A pull request gets reviewed. Tests run. The artifact is deployed through environments. Someone can usually answer who changed it and how to reverse it.
Commerce configuration is often less tidy.
A shipping threshold is changed in Admin. A tax setting is adjusted. A B2B option differs between environments. A payment setting gets recreated manually after testing.
Months later, nobody is entirely sure whether production differs from staging deliberately or accidentally.
The problem isn’t simply that somebody had to click through an Admin screen.
The problem is configuration drift.
Two environments that supposedly run the same application can behave differently because their business configuration has quietly diverged.
Adobe’s new API gives teams a better mechanism for reducing that drift.
It does not automatically give them a safe operating model.
Not all configuration belongs in the same bucket
Our view is that Adobe Commerce teams should split configuration into at least three classes.
1. Portable configuration
These are settings whose intended value should normally be consistent across environments.
Think carefully selected commerce behaviour, feature configuration or business rules that have already been tested and are supposed to behave identically after release.
These are good candidates for controlled promotion.
2. Environment-specific configuration
These values deliberately differ.
A base URL is the obvious example. So are environment-specific integration endpoints, some email settings and other infrastructure references.
The correct production value is not the tested sandbox value.
The fact that an API can copy it does not make copying it correct.
3. Secrets and sensitive operational values
Payment credentials and API credentials belong here.
Adobe specifically warns about payment-gateway keys and API credentials when moving configuration between environments.
These should generally come from the appropriate secrets-management and deployment process, not from a blind export of sandbox state.
That gives us a useful rule:
Promote intent. Inject environment. Protect secrets.
That is Tailoredd’s interpretation, not Adobe terminology.
It is a much safer mental model than “sync sandbox to production.”
Scope makes this harder than a flat configuration file
Adobe Commerce configuration is scoped.
The API supports default, website and store scope, with scopeCode identifying the relevant website or store view.
That matters for enterprise implementations.
Imagine a multi-country retailer. Tax behaviour may differ by website. Payment methods may differ by market. Store-view settings may differ by locale.
A deployment pipeline therefore cannot treat configuration as a simple collection of key-value pairs.
It needs to understand:
path + value + scope + scopeCode
as the deployable unit.
A configuration promotion process that validates the value but ignores the scope can be perfectly automated and perfectly wrong.
Permissions still apply
The endpoints require bearer-token authentication.
Adobe also says the API exposes only configuration paths visible in Commerce Admin and permitted for the requesting user’s role.
That is a useful control.
But API access changes the blast radius. A human changing one Admin setting is slow. An integration can change hundreds.
The sensible response is not to avoid automation. It is to give the deployment identity only the permissions it actually needs.
If a pipeline exists only to promote shipping configuration, there is little reason for it to receive unrestricted authority over every configuration domain.
Least privilege becomes more important as configuration becomes easier to automate.
Partial success deserves special attention
There is another implementation detail worth noticing.
Adobe’s PUT /V1/system/config can return HTTP 200 even when individual configuration items are rejected. Valid items can be saved while invalid or unauthorized items appear in the response errors array.
That means:
HTTP 200 does not necessarily mean your intended configuration state was fully applied.
A CI pipeline that checks only the status code can report a successful deployment while production is left in a partially updated state.
For commerce, that can be particularly unpleasant.
Suppose three related settings are promoted and one fails. Technically, the API request succeeded. Operationally, you may have created a configuration combination you never tested.
The deployment step should therefore validate the returned items and require an empty or explicitly accepted error set before declaring success.
Better still, follow the write with a read-back comparison of the paths you intended to change.
The deployment should have a diff
This is where the feature becomes more useful than an Admin shortcut.
Before production changes, generate a configuration diff. Not 500 settings. Only the settings being promoted.
For example:
shipping/origin/...
  sandbox:    X
  production: Y
  proposed:   X

tax/...
  sandbox:    X
  production: X
  no change

payment/.../credential
  environment-specific
  excluded
Now the reviewer is approving a commerce change, not an opaque API payload.
That makes the process understandable to engineering and commerce operations.
It also creates evidence later when somebody asks why checkout behaviour changed on Tuesday afternoon.
Adobe is extending the same pattern
The September configuration API isn’t isolated.
Adobe’s next Commerce as a Cloud Service release is currently available in Sandbox and scheduled for Production on October 6.
Among its changes are REST endpoints to create, read, update, search and delete catalog price rules. Adobe protects those endpoints using the same Magento_CatalogRule::promo_catalog permission that protects the Admin Catalog Price Rule screen. (Experience League)
That is interesting because price rules are more consequential than ordinary configuration. An integration will be able to change the conditions under which products receive discounts.
The same release adds an admin REST API for arbitrary shipping discounts and allows catalog price rules to be scheduled to a specific time of day.
This is where “API-first commerce” becomes operational rather than architectural.
The API isn’t merely serving a headless storefront. It is increasingly capable of administering the commerce engine.
Automation needs to preserve the business rule
Suppose a retailer runs a promotion:
- 20% off Category A
- India storefront only
- October 10, 09:00 to October 12, 23:59
The useful automation is not:
“AI, create a promotion.”
The useful automation is a controlled workflow in which the requested promotion becomes a deterministic rule, is validated against the target website and dates, receives the required approval, and is then applied through the platform’s supported interface.
Whether the initial instruction came from a human form, CI pipeline or AI assistant is secondary. The commerce system should remain responsible for enforcing the rule.
That distinction is increasingly important as commerce APIs become callable by more types of clients — and is directly relevant to the governance boundaries we discussed around Salesforce AIforce.
This is also where AI becomes less magical
It would be easy to turn Adobe’s expanding REST surface into another agentic-commerce story.
We won’t.
An AI agent could eventually sit above these APIs, but the architecture question exists without AI.
- Who may alter a promotion?
- Which settings may cross environments?
- What requires approval?
- What should be read-only?
- How do we know what changed?
- How do we reverse it?
Those are deployment and governance questions first. AI merely makes answering them more urgent.
This connects to the same principle behind Tailoredd’s own approach to AI agent boundaries in commerce: read-only tool connectivity by default, mutating actions only through explicit human approval gates.
A practical promotion pipeline
If we were reviewing an Adobe Commerce implementation using the new configuration API, the workflow we would want to see is roughly:
1. Select — Retrieve only the paths intended for promotion rather than dumping every available setting.
2. Classify — Mark each path as portable, environment-specific or sensitive.
3. Diff — Compare tested sandbox state against current production state.
4. Review — Require a human approval for meaningful production changes.
5. Inject — Resolve production-specific values from their proper environment or secret source.
6. Apply — Call the supported production API using a least-privileged integration identity.
7. Validate — Inspect item-level errors, then read the changed paths back from production.
8. Observe — Run targeted smoke tests around the affected commerce behaviour.
That is more work than pressing “copy.”
It is also why the API is valuable. It lets teams build repeatability around something that previously depended too heavily on human memory.
What not to do
Do not retrieve every sandbox configuration value and send the entire response to production. Adobe explicitly warns against that pattern for environment-specific values.
Do not put credentials into source control because configuration has become deployable.
Do not treat an HTTP 200 as proof that every requested change succeeded.
Do not ignore scope.
Do not let a generic automation identity own more Commerce permissions than its job requires.
And do not assume this API applies to every Adobe Commerce deployment model. The feature discussed here is documented for Adobe Commerce as a Cloud Service. Adobe explicitly directs Adobe Commerce on cloud infrastructure and on-premises users to their separate release documentation.
That boundary is important.
The bigger shift
Commerce teams have spent years bringing storefront code under increasingly mature engineering practices. Configuration has often lagged behind.
Adobe’s September release creates an opportunity to narrow that gap.
The valuable outcome isn’t “we no longer have to click the same settings twice.”
It is:
We can define which commerce configuration is portable, review its differences, deploy it deliberately and verify the resulting production state.
That is a much more useful capability.
The API is the easy part. The operating model around it is what determines whether configuration automation reduces risk or simply automates configuration mistakes.
Whether you run Adobe Commerce, Salesforce Commerce Cloud, or another platform, the underlying architecture question is the same: which business configuration deserves deployment discipline, and which should remain operationally managed?
This article reflects Tailoredd’s architectural interpretation of Adobe’s documented Commerce as a Cloud Service capabilities. The October 2026 functionality discussed above is available in Sandbox as of October 3 and is scheduled by Adobe for Production on October 6. Verify current Adobe release documentation before implementing in production.
